Timeline · One job
job-10 · Red fox · 38.9 ms
Recorded on 2 Oct 2026 on the live runtime. Connecting to the live runtime.
Ctrl + wheel zooms, drag pans, ← → step through events.Tap a bar or marker for details; + and − zoom, then drag to pan. Open in Perfetto: copy the trace, save it as trace.json, drop it on ui.perfetto.dev.
All 4 events in time order
| ms | track | what | detail |
|---|---|---|---|
| 0.000 | Jobs | job-10 | completed after 38.6 ms |
| 8.60 | CPU | mobilenet FP32 | 12.0 ms · job-10 |
| 21.6 | Router | Router decision | CompositeRouter: LatencyBudgetPolicy: remaining budget 21.2 ms < threshold 30.0 ms; downgrading to INT8 for node 'bert_tiny' |
| 35.2 | GPU_SIM | bert_tiny INT8 | 3.23 ms · job-10 |
Result
What the job produced
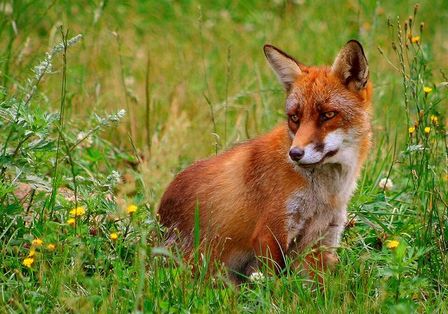
mobilenet says
red fox
77.5% confidence
- red fox77.5%
- dhole14.4%
- kit fox4.3%
- red wolf3.0%
- grey fox0.2%
| node | lane | precision | ms |
|---|---|---|---|
mobilenet | CPU | FP32 | 12.0 |
bert_tiny | GPU_SIM | INT8 | 3.23 |
| job | budget 42.0 ms | 38.9 | |
Router decisions
bert_tinyLatencyBudgetPolicyremaining budget 21.2 ms < threshold 30.0 ms; downgrading to INT8 for node 'bert_tiny'
bert_tiny embedding
Embedded a photo of a red fox
. The first 16 of 128 values:
- -1.000
- 0.010
- -0.999
- 0.982
- -1.000
- 0.779
- -0.994
- -0.617
- 0.059
- 0.025
- -0.576
- 0.066
- -0.001
- 1.000
- -0.866
- -0.575
Benchmark
FP32 vs INT8, measured
Modal container, x86-64✓AVX2 present–AVX-512 absent–AVX-512 VNNI absent–AVX-VNNI absent
| model | FP32 p50 | INT8 p50 | FP32 INT8 | INT8 speed-up | on AMD Ryzen 9 6900HX |
|---|---|---|---|---|---|
| MobileNetV2 · static QDQ | 11.4 | 11.5 | 0.99x | 0.93x | |
| bert_tiny · dynamic | 0.323 | 0.259 | 1.25x | 1.13x |
No VNNI on this CPU, so INT8 runs on AVX2 kernels and comes out at 0.99x FP32: no real gain, as on the reference Ryzen. That is why precision is a runtime policy rather than a constant.
Recorded machine: loomcore_bench, 20 warm-up and 100 measured runs per variant, 2 Oct 2026; ONNX Runtime 1.30, one intra-op thread per session (the scheduler supplies the parallelism). Latency only: the INT8 models are not checked for accuracy. Reference numbers from docs/BENCHMARKS.md.
Controls
Drive the runtime
Binding: admission control rejects a job that cannot fit, and the reaper cancels one that runs out of time.
Checking the live runtime…
Graph
mobilenet → bert_tiny
mobilenetCPUMobileNetV2 · image classifier
bert_tinyGPU_SIMBERT-tiny · text encoder
Router chain
In order. A skip ends the chain; otherwise the first policy to set precision or lane wins. Changes apply to the next run, which hot-swaps the graph to the new router first.
- 1
circuit-breakerCircuitBreakerPolicy(0.5, 4, 2000)
Reads the node's recent success and failure outcomes; skips a node whose error rate reached 50% over at least 4 runs; lets one probe through after 2 s.
- 2
bulkheadBulkheadPolicy(6)
Reads how many requests for the node are in flight; sheds (skips) a request once 6 are already in flight for that node.
- 3
confidence-gateConfidenceGatePolicy(0.85)
Reads mobilenet's softmax confidence for this image; skips bert_tiny once mobilenet is at least 85% sure; there is nothing left to describe.
- 4
precision-plannerPlannedPrecisionPolicy()
Reads measured FP32 and INT8 p95 per node, and the job's budget; solves a 0/1 knapsack over the critical path for which nodes to run INT8 so the job fits.
- 5
latency-budgetLatencyBudgetPolicy(30)
Reads the job's remaining time budget; drops a node to INT8 once less than 30 ms of the budget is left.
- 6
load-awareLoadAwareBackendPolicy()
Reads the CPU and GPU_SIM queue depths; sends the node to whichever lane has the shallower queue.
Scheduleradmission controldeadline cancellationprecision planningEDF lanes
Claims
Every claim, next to what checks it
From docs/CLAIMS.md. Each links to the test case or program that asserts it.
| # | claim | checked by |
|---|---|---|
| 1 | The full test suite passes | CMakeLists.txt |
| 2 | A job's promise is settled exactly once, even under a deadline reaper racing a node's natural completion (no std::terminate) | test_scheduler_deadlines.cpp:173 |
| 3 | Batching never mixes incompatible non-batch shapes for the same node | test_scheduler_deadlines.cpp:80 |
| 4 | Scheduler::shutdown() actually stops accepting new jobs (not a no-op) | test_scheduler_deadlines.cpp:119 |
| 5 | Admission control rejects a job the precision planner judges undeliverable, and dispatches nothing first | test_scheduler_deadlines.cpp:136 |
| 6 | The precision-downgrade knapsack finds the true minimum-quality-loss set, which a savings-only greedy would not | test_planner.cpp:73 |
| 7 | The circuit breaker lets through exactly one probe after cooldown, never more, under concurrent load | test_router.cpp:223 |
| 8 | Runtime::reloadGraph hot-swaps the graph under continuous concurrent load with zero jobs lost | test_runtime_reload.cpp:48 |
| 9 | The same hot-swap holds against the real mobilenet+bert_tiny pipeline, with per-swap timing reported | examples/reload_demo.cpp |
| 10 | The reference pipeline runs end to end (real image → classification → confidence-gated embedding) and reports real per-node p50/p95 | examples/run_example.cpp |
| 11 | INT8 MobileNetV2 is measurably *slower* than FP32 on the reference (non-VNNI) machine — not fabricated, not silently skipped | benchmarks/latency_bench.cpp |
| 12 | The ORT dependency is fully encapsulated: the benchmark links and runs with no ONNX Runtime include/link dependency of its own | benchmarks/latency_bench.cpp |
| 13 | The C API is a real, separate consumable surface: a pure-C translation unit links and runs against it with no C++ Loomcore headers | bindings/c/smoke_test.c |
| 14 | The installed package is consumable via plain find_package(Loomcore) — not just "it builds in-tree" | examples/consumer |
| 15 | CI builds and tests both platforms (Windows + Linux) on every push/PR | .github/workflows/build.yml |
| 16 | A run's JSON-lines log converts to a real, structurally valid Perfetto/Chrome Trace Event Format timeline — lane tracks, per-execution duration bars, routing markers, DAG flow arrows | test_perfetto_export.cpp |